
Debugging issues with AI tool calls can be a frustrating experience. You’ve defined your tools, crafted your prompts, and your agent is supposed to call them, but sometimes it just… doesn’t. Or it calls them incorrectly. Or it calls them, but the output isn’t what you expect. I’ve spent a fair bit of time wrestling with these kinds of problems, and I’ve found that tool call failures generally fall into three distinct categories, each requiring a different diagnostic and resolution strategy.
The first point of failure is before the tool is even invoked: the model’s reasoning. This is where the AI decides whether to call a tool and which tool to call, along with the arguments. If your agent is hallucinating tool names, or calling a general search tool when a specific internal API is clearly more appropriate, the problem lies here. The fix often involves refining your tool descriptions. Be explicit, provide clear examples in your prompt, and ensure the tool’s purpose is unambiguous. Sometimes, a slight rephrasing of the tool description, or adding a negative constraint (e.g., “only use this tool for X, do not use for Y”), can make a significant difference. It’s about guiding the model’s decision-making process more effectively.
The second stage of failure occurs during the actual tool invocation. The model has decided to call a tool, and it has formulated the arguments, but the call itself fails. This usually manifests as an error from the tool’s backend: a malformed JSON payload, missing required parameters, or incorrect data types. This isn’t an AI reasoning problem; it’s an integration problem. My go-to here is to log the exact payload being sent to the tool. Is the AI sending a string when an integer is expected? Is it using a different key name than the API expects? Often, the solution involves adjusting your prompt to steer the model towards generating the correct argument format, or, if you have control over the tool’s wrapper, adding more robust input validation and type coercion. You might also need to explicitly instruct the model on the expected format of complex arguments, sometimes even providing a JSON schema within the prompt itself.
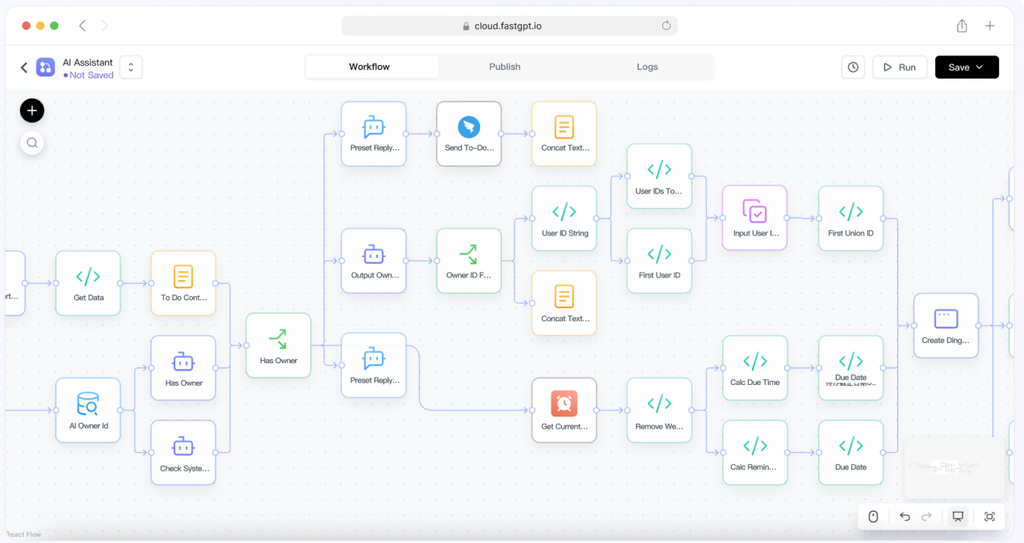
The third, and often most subtle, failure point is when the tool executes successfully, but the output is misinterpreted or mishandled by the AI. The tool did its job perfectly, returned valid data, but the agent either ignores it, misinterprets its meaning, or fails to use it to formulate a coherent response. This is a model reasoning problem again, but it’s about interpreting external data rather than deciding on a tool. Here, the solution often involves improving the clarity of the tool’s output and refining the agent’s subsequent instructions. Can the tool output be simplified? Can you add a summary to complex outputs? For instance, instead of returning a raw JSON blob of weather data, can the tool return a concise sentence like “The current temperature in London is 15°C with light rain”? Sometimes, explicitly instructing the AI on how to use the tool’s output in its final response can also help. I’ve found that understanding these distinct failure points has dramatically improved my debugging efficiency when building agents. For more on the inherent variability in AI responses, I found the FastGPT project provided some useful insights that resonate with these observations.
It’s worth noting that while these categories are distinct, they can sometimes overlap. A poorly described tool might lead the AI to generate malformed arguments, blurring the line between stage one and two. Always start by isolating the exact point of failure, which often means logging everything: the prompt sent to the model, the model’s raw response (including tool calls), and the actual requests/responses from your tools. This granular visibility is key to quickly identifying where the breakdown occurs.
